Decision 2.0 Qwen Models: Semantic Routing Setup and Evaluation Guide
Use Decision 2.0 Qwen-derived models for semantic routing. Compare checkpoints, run typed decisions, calibrate thresholds and measure total application cost.

Written by Fan Chuanyu
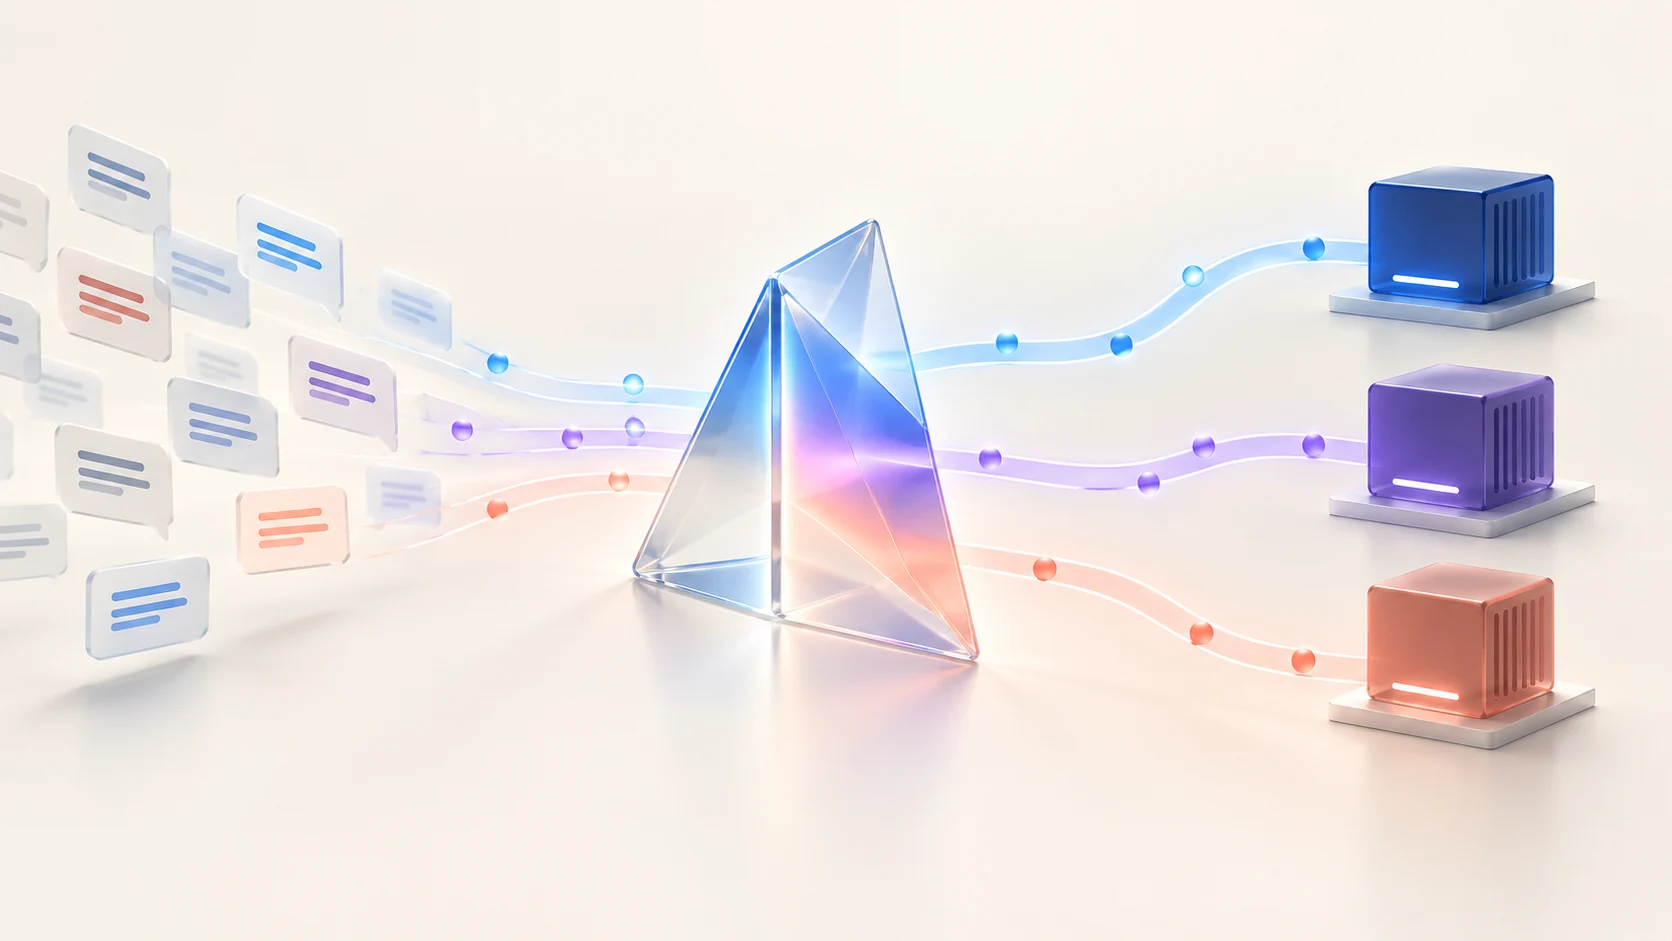
Decision 2.0 gives an application a way to classify a request before spending resources on a longer answer. Its checkpoints return probabilities for typed decisions, so a router can choose a backend, identify a condition or estimate complexity without asking a chat model to write an explanation first.
The family belongs to the vLLM Semantic Router team and includes Qwen-derived checkpoints. This guide reviews six published model cards as of October 4, 2026. It explains how to start an evaluation; it does not report a hardware benchmark or claim that a routing policy has already reduced production costs.
Separate the decision from the answer
A decision model takes a state, expressed as text or JSON, together with questions about that state. Decision 2.0 supports choices, yes/no decisions and scores. Several questions about the same input can be answered in one forward pass, with probabilities rather than generated response text. The Sol model card documents this interface.
For a support assistant, the decision might be which service should receive a request. The selected service still needs to retrieve information or produce the final answer. For a coding assistant, the decision could distinguish a short explanation from a task that needs repository tools. The router is one component of that workflow, not its replacement.
Keep the routing vocabulary tied to concrete behavior. Labels such as “fast” and “advanced” are too vague unless your application defines what those routes actually handle. Write criteria around task requirements and supported capabilities, then evaluate those criteria against real requests.
Compare checkpoint size and context
The following table records the six reviewed cards. Names are rounded family labels; the cards report different parameter counts in some cases.
| Checkpoint | Reported parameters | Context tokens | Selection consideration |
|---|---|---|---|
| Kai-0.6B | 0.60B | 8,192 | Smallest of these reviewed checkpoints |
| Eos-0.8B | 0.75B | 16,384 | Longer input budget than Kai |
| Sol-2B | 1.88B | 16,384 | Starting point used in the example below |
| Nox-4B | 4.21B | 16,384 | Compare quality against smaller candidates |
| Lux-9B | 7.94B | 16,384 | Budget more memory before serving |
| Vega-27B | 29.37B | 32,768 | Adapter checkpoint with additional loading requirements |
The Vega card identifies Qwen3.8-27B as its base and calls for PEFT in the installation. Other cards identify either a Qwen base or an earlier Decision checkpoint. This is a Qwen ecosystem application developed by the Semantic Router team, rather than a new Alibaba chat-model release.
Start with a size your serving environment can accommodate. A larger checkpoint only helps if its improvement on your routing tasks justifies loading, inference and queueing costs. The table is an inventory, not a ranking from our own tests.
Run a typed decision with a pinned revision
The Sol card specifies these dependencies:
pip install "transformers>=5.17" torch safetensors
The example uses the documented system_one interface with original task criteria. It pins the reviewed model revision because loading with trust_remote_code=True executes code supplied by the repository. Review that code before running it in your environment.
from transformers import AutoModel

model = AutoModel.from_pretrained(
    "vllm-sr/Decision-2.0-Sol-2B",
    revision="64235bef55dad29387dd16da7c90e038bf2f0972",
    trust_remote_code=True,
)
result = model.system_one(
    state="Explain what this Python function does; do not modify files.",
    questions={
        "route": {
            "type": "choice",
            "instructions": "Select the backend suited to the request.",
            "criteria": {
                "text": "Explanation or rewriting without repository actions",
                "coding_agent": "Inspecting, editing or testing repository files",
            },
        },
        "needs_tools": {
            "type": "noul",
            "instructions": "Does the request require repository tools?",
        },
        "complexity": {
            "type": "score",
            "instructions": "Estimate the work required by this request.",
            "criteria": ["Routine", "Moderate", "Complex"],
        },
    },
)
print(result["answers"])
noul is the model card's type name for a yes/no question. This example deliberately prints the returned answers rather than inventing a response structure or a fixed confidence value. Inspect the actual output before building an adapter around it.
This local call also does not create an HTTP serving endpoint. Deployment through the Semantic Router project requires its own configuration and integration work. Keep the model-loading experiment separate from gateway readiness.
Calibrate the routing policy on labeled requests
Build a representative set of requests and label the route each should take. Include ambiguous cases, unsupported tasks and the languages your application receives. Hold some requests aside for evaluation so that editing the criteria does not quietly turn the test into a memorized development set.
Compare the chosen route against the label. Pay particular attention to mistakes that send difficult tasks to a backend unable to complete them. An apparently cheaper route can become expensive after retries or manual correction.
A returned probability does not by itself establish a calibrated confidence level for your traffic. Choose a threshold only after examining the errors. A practical policy may send uncertain cases to a capable default backend while recording them for later review. That threshold and fallback behavior are application decisions, not universal model settings.
Also test consistency between questions. If the route requests a coding agent but the tool decision says tools are unnecessary, record the disagreement. You can simplify overlapping criteria or define a deterministic resolution rule before the router controls live traffic.
Count the entire request cost
Measure the router's load time, inference time and memory use alongside the selected backend's work. Add retries and fallback calls to the comparison. Published model-card latency is evidence about the authors' test conditions; it is not your gateway's end-to-end response time.
The useful comparison is cost per acceptable completed task, with latency at the percentiles your users experience. Replacing a chat-based classifier may reduce one part of that cost, but a poorly chosen route can erase the saving downstream.
For a hosted typed-decision option, our Cloudflare Clef guide covers a separate service and API contract. Do not assume its schema or model identifiers are interchangeable with Decision 2.0.
Choose the smallest checkpoint that passes
Decision 2.0 is useful when an application needs repeatable routing decisions before generation. Start with explicit criteria, inspect real outputs and evaluate on labeled requests. Expand the checkpoint size only when the measured quality improvement warrants it. The reviewed cards list Apache-2.0 licensing; retain the notices and check the exact assets selected for deployment.
Frequently asked questions
Does Decision 2.0 generate a chat answer?
Its documented interface returns probabilities for typed decisions without generating text. Another component produces the user-facing answer.
Does the 27B label mean exactly 27 billion parameters?
No. The reviewed Vega card reports 29.37B. Use card values for capacity planning rather than assuming family names are exact counts.
Can I use the highest-probability route immediately?
You can implement that policy, but evaluate its errors and fallback behavior first. A probability alone does not prove that the chosen backend will complete the task.

 Fast Pivot — Access hundreds of AI models from a single API — competitive pricing, reliable uptime, enterprise-grade infrastructure.